For large websites, checking that every page loads correctly is a huge challenge. I built a Sitemap QA Crawler in Python that automatically validates all URLs listed in a site’s sitemap.
The crawler is resilient and production-ready:
-
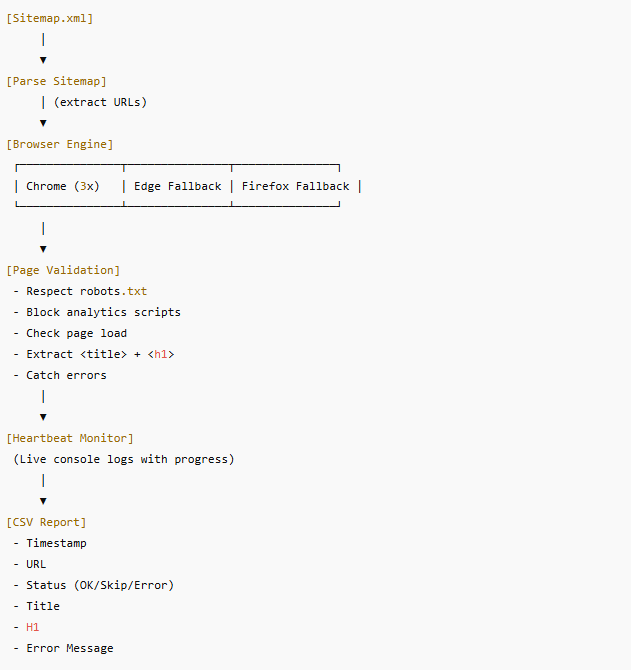
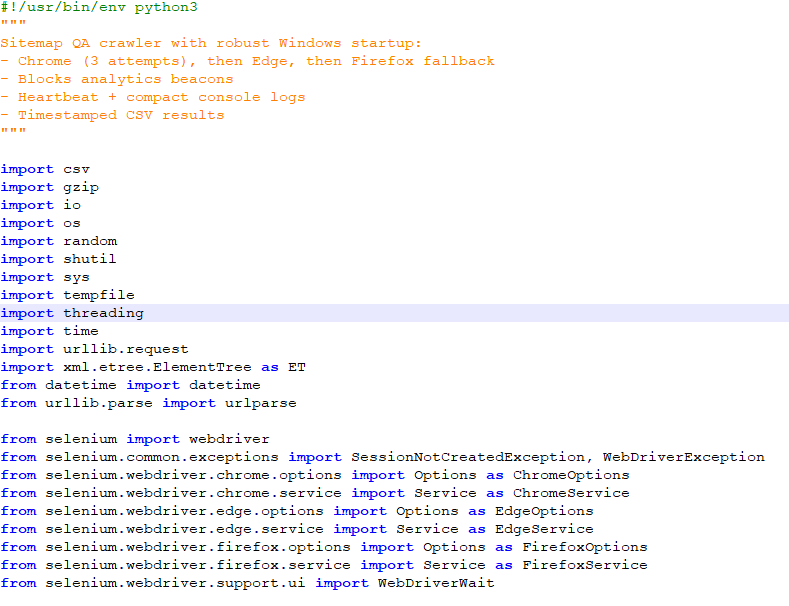
Multi-browser startup strategy: tries Chrome (3 different modes), then Edge, then Firefox as fallback.
-
Robust crawling: respects robots.txt, retries intelligently, and logs all outcomes.
-
Lightweight performance: adds randomized delays between requests, runs headless browsers, and maintains a heartbeat log so progress can be monitored live.
-
Privacy-first: blocks common analytics and tracking scripts during the crawl to avoid polluting site metrics.
-
Detailed output: generates timestamped CSV reports with status, title, first <h1> content, and error messages for each URL.
The tool is designed for quality assurance teams, SEO audits, and web developers who need a reliable way to crawl, test, and log the health of large websites without relying on third-party services.
Have an idea that needs to work?
Discuss the next practical step with De Wilde ICT Solutions.
Contact us