This project delivers a robust CSV cleaning pipeline designed to normalize and validate country fields while ensuring strict de-duplication. It is optimized for large-scale datasets where reliability and resumability are critical.
Key features:
-
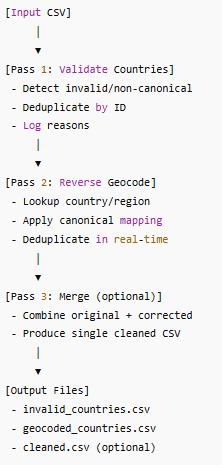
Pass 1: Scans input data, detects invalid or non-canonical country names, and exports them for review.
-
Deduplicates by id both against previous runs and within the same session.
-
Logs detailed reasons for invalid entries.
-
-
Pass 2: Attempts to auto-correct invalid countries via reverse geocoding (Nominatim/OSM).
-
Dedupes output in real-time so no run can emit duplicates.
-
Applies canonical country/region mappings where available.
-
-
Pass 3 (optional): Produces a fully cleaned merged CSV with consistent, canonical countries, validated regions, and all fixes applied.
-
Resume support: Safe to restart without overwriting progress.
-
Strictness options: Enforce ISO region validation (--strict-region) or allow conservative typo correction (--allow-fuzzy).
This cleaner ensures a trustworthy, deduplicated dataset, even when processing millions of rows.
Have an idea that needs to work?
Discuss the next practical step with De Wilde ICT Solutions.
Contact us